Warehouse UX · open engine · your AWS
A Snowflake-grade warehouse. On stock Spark. In your account.
Warehouse UX on stock Apache Spark. Metered by the second. In your own AWS account.
Three teams, one product.
Flashpoint is for people who already run Spark, or already pay for the shape Snowflake taught everyone to expect. Step through them.
You already run Spark. This gives it a warehouse face.
The engine stays Apache Spark. What changes is the layer your team works in.
Spark today
- Notebooks stapled to a long-lived cluster
- Job logs instead of a query profile
- A cluster bill you cannot attribute per query
Spark with Flashpoint
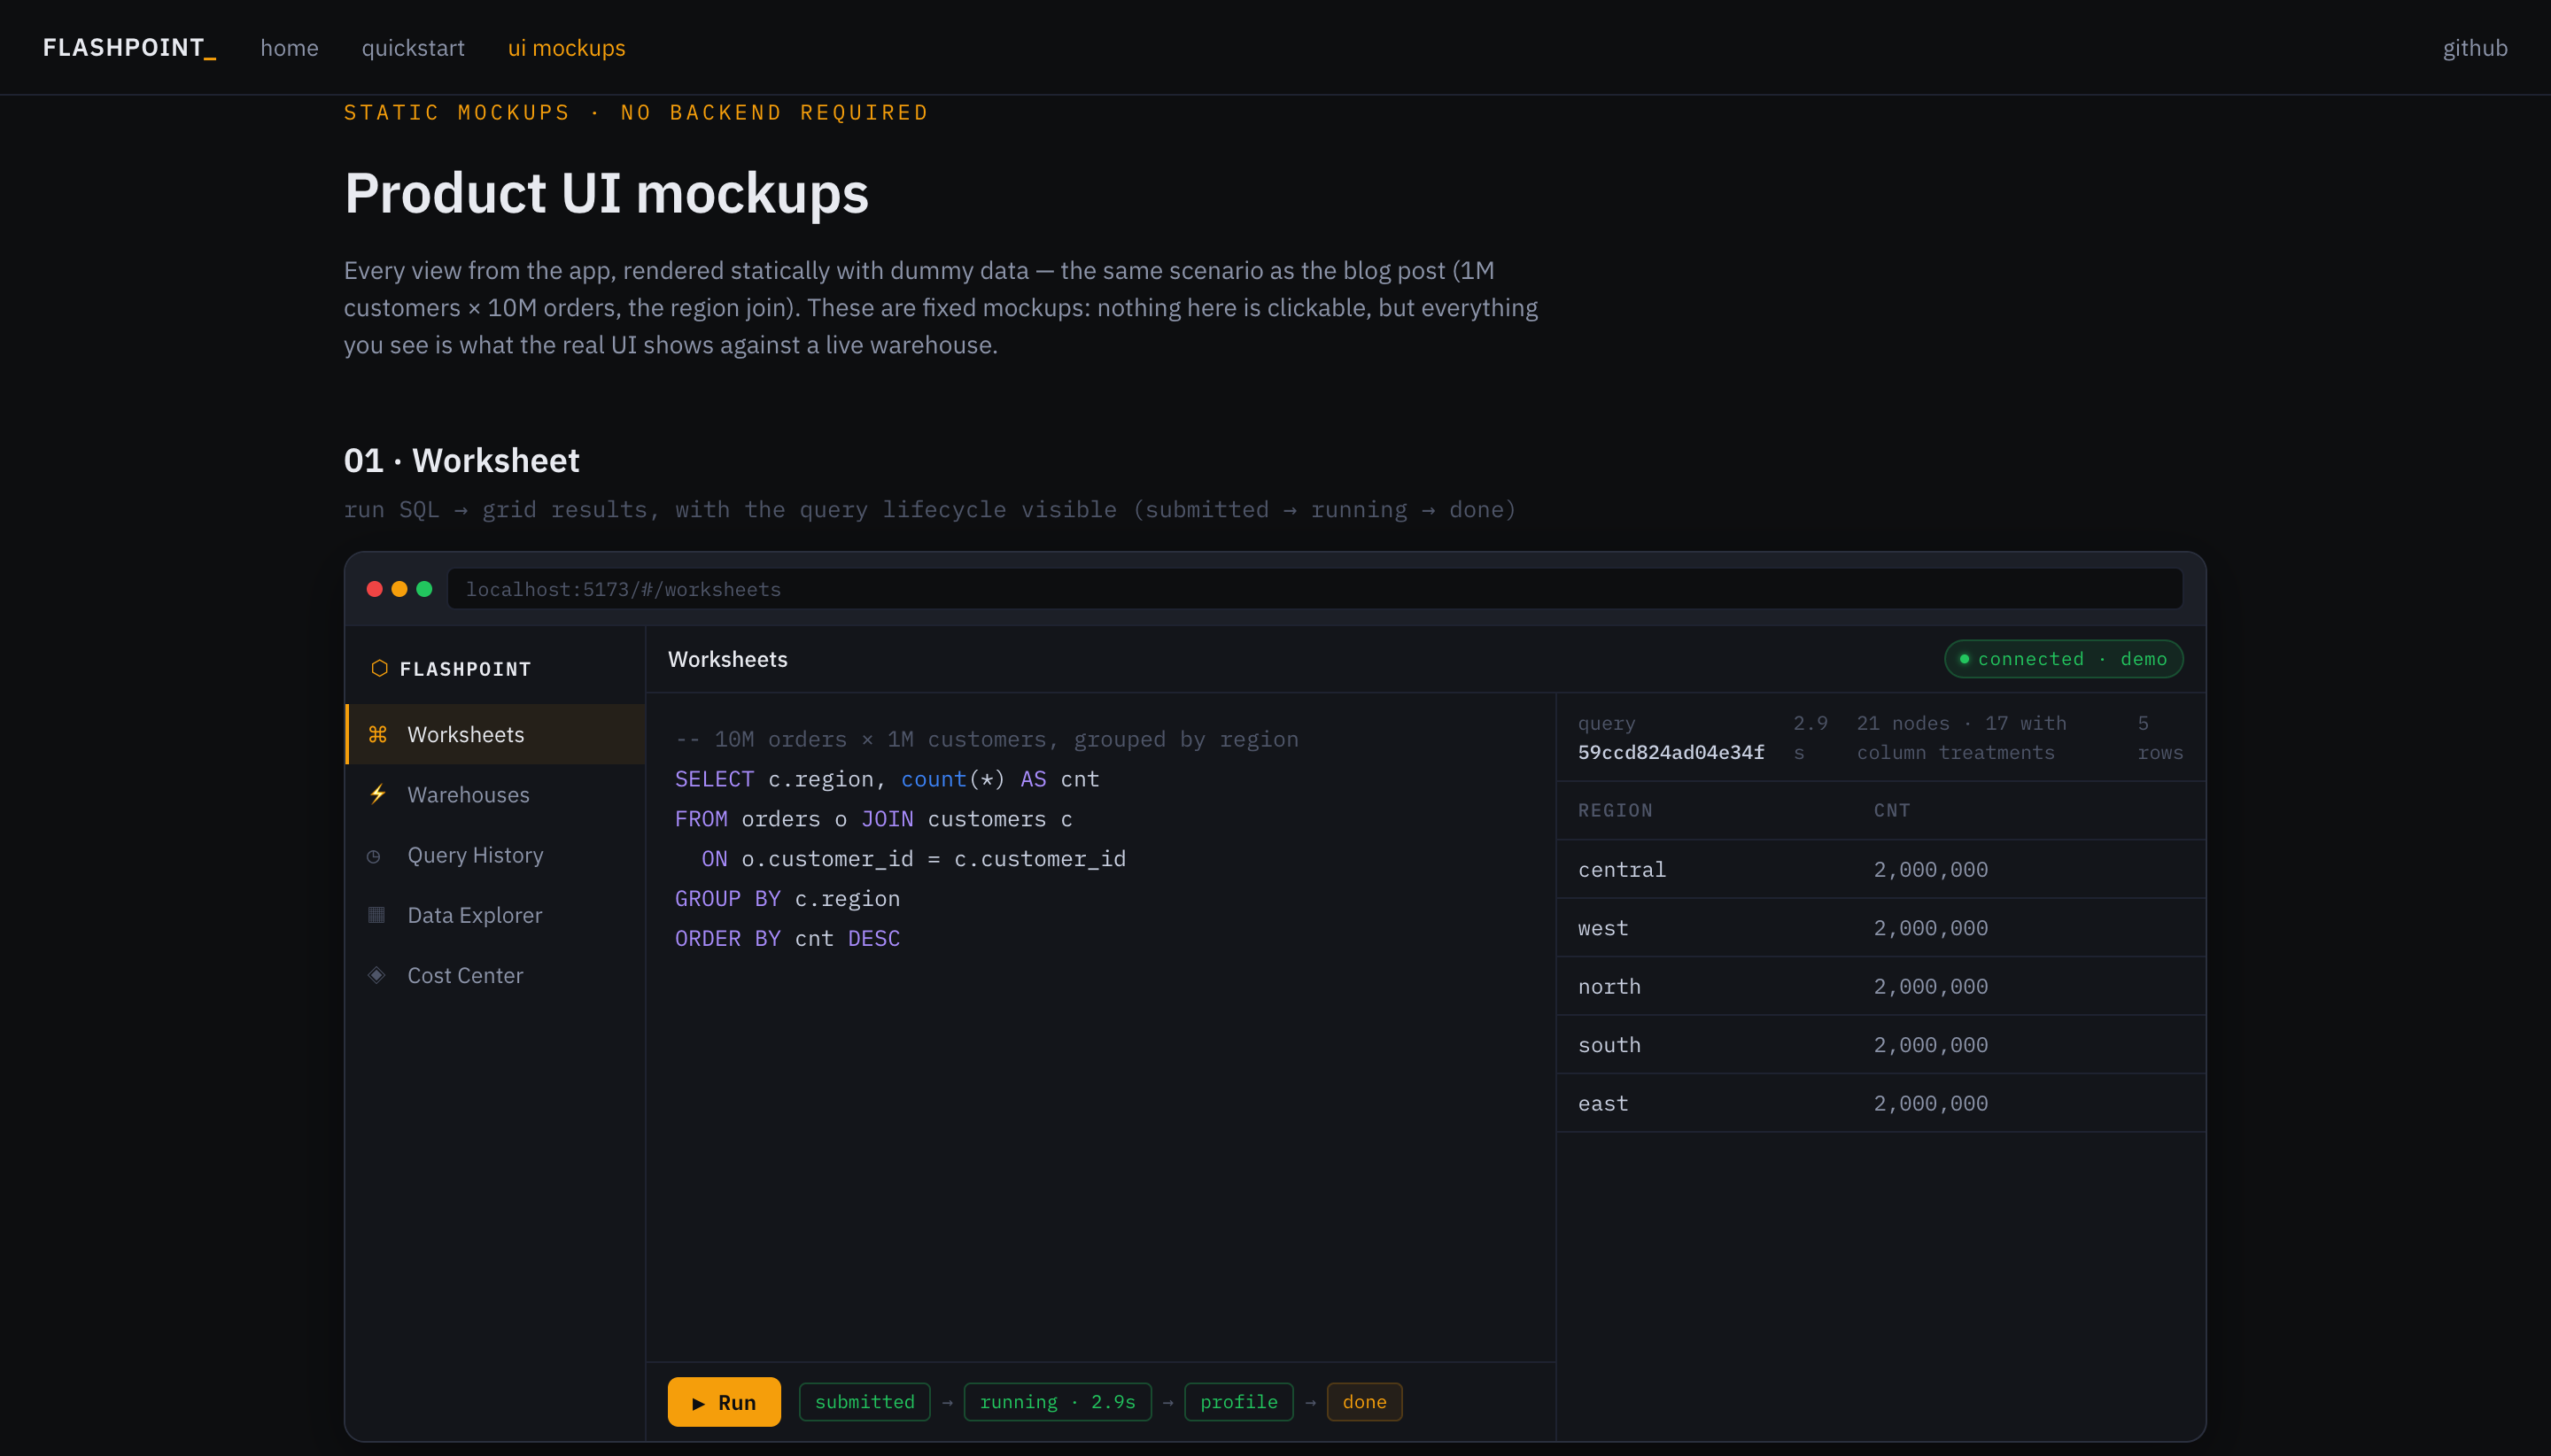
- A worksheet, and warehouses you create, suspend and resize
- An operator-tree query profile for every query
- Per-second metering, and a cost center beside the AWS bill
It plugs into what you already run.
No new engine to learn and no rewrite. A warehouse exposes one Spark Connect endpoint and one REST control plane, and everything else in your stack already speaks those.
Clients
- Any Spark Connect client, including PySpark and notebooks
- SQL through the REST gateway, or straight to the endpoint
- Existing DataFrame and Spark SQL code, unchanged
Automation
- Airflow, CI or a script drives lifecycle and queries over the REST API
- Every query profile is a stable URL you can paste into a PR or a ticket
- Metering per warehouse, readable next to the AWS bill
An hour of the smallest size.
Per compute-second, and only while a warehouse runs. A suspended warehouse bills nothing.
Data never leaves your account.
Gateway, driver, executors and results all run inside your VPC, on your IAM and your S3, reached over an endpoint you open.
Where the query spent its time.
Not a job log. The operators ranked by duration, the slow one first.
- Find the slow step, not the slow job
- Share any query as a link
- See what the query cost
You pay for the seconds it runs.
Metered per compute-second while a warehouse is up. Suspended warehouses bill nothing.
- Per compute-second, no minimum
- Suspended is $0 compute
- Live meters beside the AWS bill
Create it, run it, suspend it.
A warehouse starts on demand and stops when idle. You never manage a node.
Straight answers.
How close is it to Snowflake?
It copies the shape of the product: the warehouse, the worksheet, the query profile, the per-second billing. Your data stays in open formats, so there is nothing to migrate back out of.
What does it cost?
Per compute-second on a running warehouse. Suspended warehouses bill nothing. Sizes run on a published rate card from $0.08/h for one executor. There are no credits and no per-seat fees.
Where does my data live?
In your AWS account: Iceberg tables and Parquet results on your S3, catalog in your Glue, state in your DynamoDB. Nothing leaves the account.
Can I use it from a notebook or pandas?
Yes, anything that speaks Spark Connect can attach to a warehouse's gRPC endpoint. The REST gateway is there for SQL and lifecycle calls.
Waitlist
Be there when signup opens.
Early access opens in batches. Leave an address and you will get one email when a batch opens, nothing else, and no newsletter.
One email when signup opens. Addresses are stored with the mailing-list provider and never sold or shared.